

AI adoption is moving fast, and the teams responsible for managing its costs are trying to keep up. Between new models, agentic applications and changing pricing structures, even figuring out what the organization is using can be a challenge.
On our blog we’ve discussed executive and short term strategies and concepts for managing AI costs. Our FinOps Fridays podcast has several past and upcoming episodes sharing experiences and best practices. But where does FinOps fit, and how does it work alongside Tokenomics?
The answer starts with how your organization runs AI. Each approach gives you different cost drivers and different controls. FinOps has a role in all of them.
Open weight vs. closed weight vs. hosting
Open-weight models make their trained weights available for organizations to download and use under specific licensing terms. They are not necessarily open source, and you don’t have to host them yourself. Managed inference providers also offer access to open-weight models.
Closed-weight models keep their weights private. Organizations typically access them through APIs or applications, with the provider operating the underlying infrastructure.
There are a variety of hosting strategies for open weight models, where FinOps capabilities can apply to varying degrees. This is distinct from closed weight models however, which can only be used via agentic applications.
These distinctions matter, but for FinOps practitioners, the most direct and practical questions to answer is: What are we paying for, and what can we control?
| AI deployment | What organizations pay for | Applicable Capabilities |
|---|---|---|
| Self-hosted models | GPUs, compute, storage, networking and operations | Infrastructure allocation, capacity planning, utilization and rate optimization |
| Managed models and inference clouds/services | Tokens, requests, provisioned capacity and supporting services | Usage allocation, forecasting, purchasing decisions and unit economics |
| AI applications and agentic tools | Licenses, seats, credits and usage charges | License governance, usage monitoring, allocation and value measurement |
Hosting models? The infrastructure still matters
When open-weight model infrastructure runs in the cloud, much of the work will look familiar to a FinOps team.
Managing AI is more involved than adding a few tags. Shared models can serve several teams and applications. GPU capacity can be expensive to leave idle. Demand can change quickly, and meeting performance requirements may mean keeping capacity available even when it isn’t fully used.
This is where infrastructure economics and tokenomics in terms model efficiency and output value need to come together. Reducing token consumption won’t necessarily lower your bill if the same GPUs are still running. Likewise, cutting infrastructure costs won’t help if the service becomes too slow to use.
FinOps and engineering teams need to connect the cost of running the service with the work it performs. That means looking beyond tokens to the full cost of delivering a useful result.
Managed inference changes the controls, not the need for FinOps
With managed inference, the provider takes on more of the operational work. Your team may have less visibility into the infrastructure, but it still needs to understand what drives AI costs and consumption
Depending on the service, charges may be based on tokens, requests, provisioned capacity or a combination of these. The available billing detail and optimization options will vary, too.
Where FinOps meets Tokenomics
Tokenomics brings a closer look at model and token economics: which model fits the task, how much context it needs, whether caching can reduce repeated processing and how many calls an agent makes to finish its work.
The goal is to achieve a desired level of value for the task at an acceptable cost and speed, balancing cost with quality of output. Token counts matter, but so does what those tokens accomplish. For self-hosted models, efficiency affects infrastructure demand and capacity. For applications, it can affect usage charges more directly.
FinOps practitioners bring those insights into conversations about budgets, ownership, shared costs and investment decisions. AI introduces new cost drivers while established FinOps practices remain relevant. The Tokenomics foundation is also working closely with the industry via focus groups to help build and adapt best practices as AI adoption journeys mature.
Start with what you can see, then build from there
Bring your available AI cost and usage data together, and establish ownership of AI costs. Then work with engineering and business teams to agree on what success looks like.
FinOps was built for cloud and AI brings new challenges but its purpose remains familiar: help organizations understand what they spend, make better decisions and get more value from the technology they use.
IBM brings FinOps into the age of AI
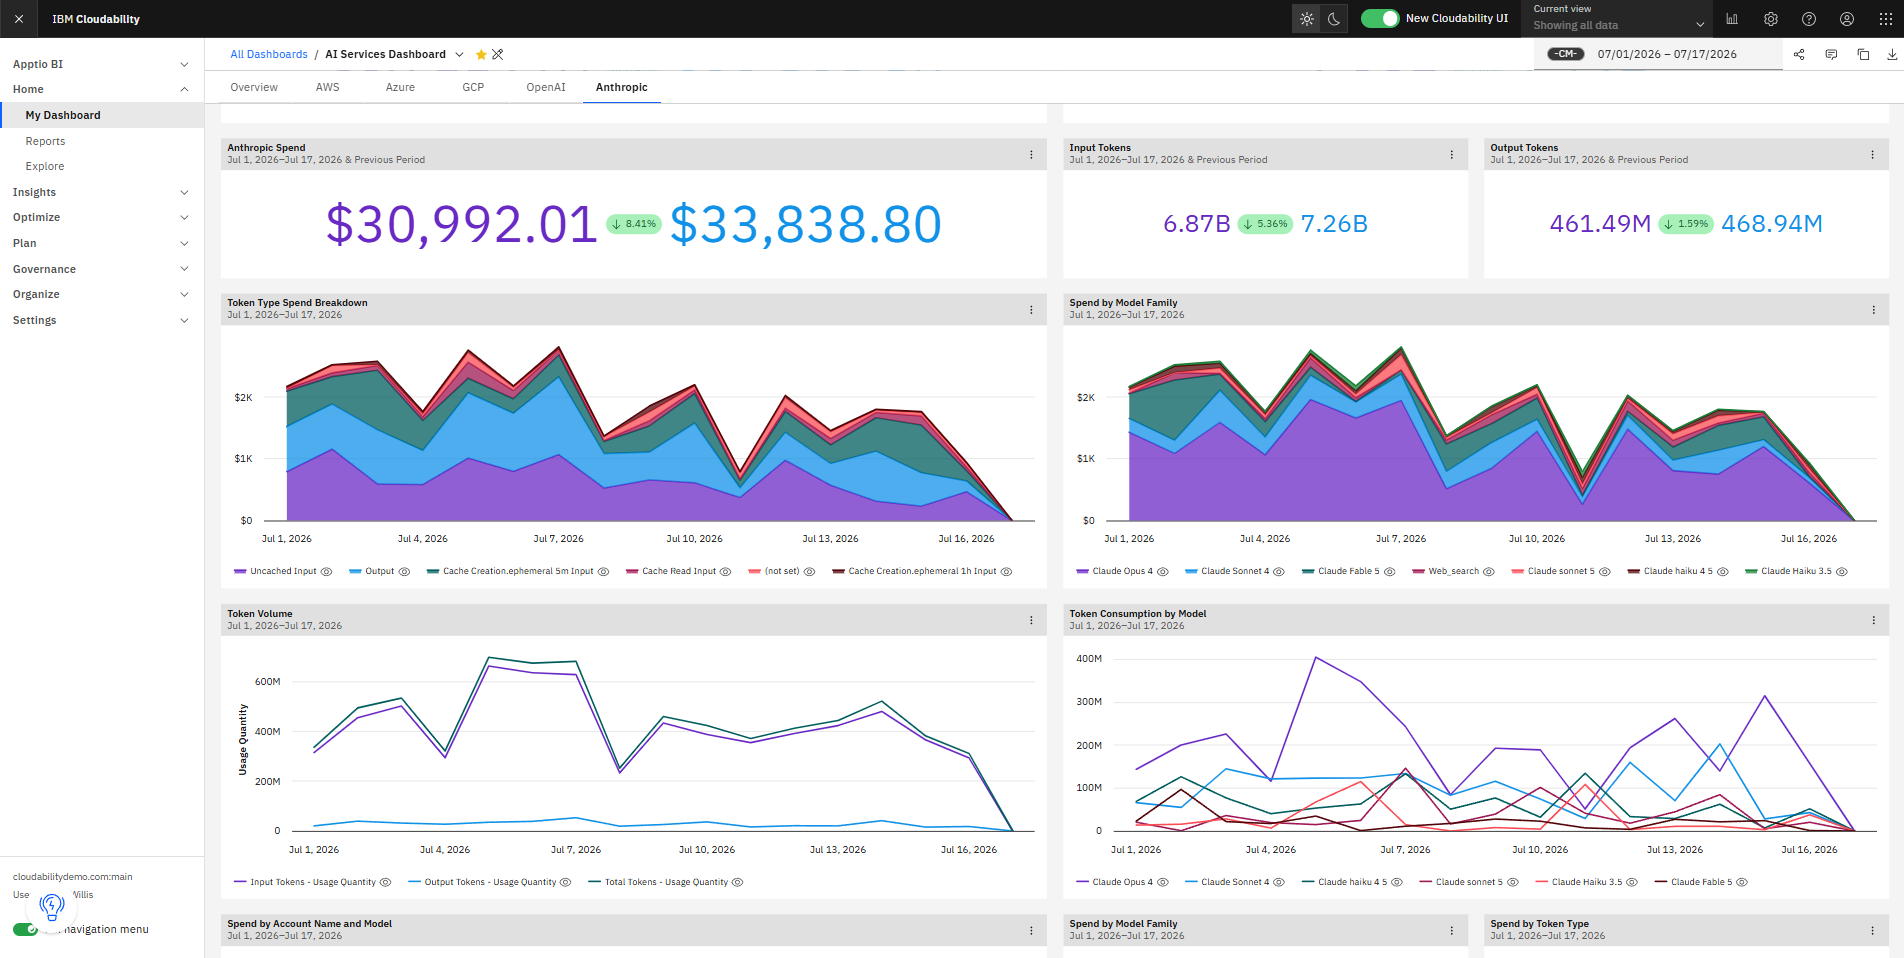
IBM Cloudability helps practitioners put that approach into practice by bringing model utilization, token consumption and associated costs into view across teams and workloads. By allocating shared AI expenses to business units, products and applications, it helps teams understand the AI costs allocated to them and take responsibility for it. With Cloudability, teams can evaluate cost per outcome, identify where to improve and make informed decisions about how to improve AI value.
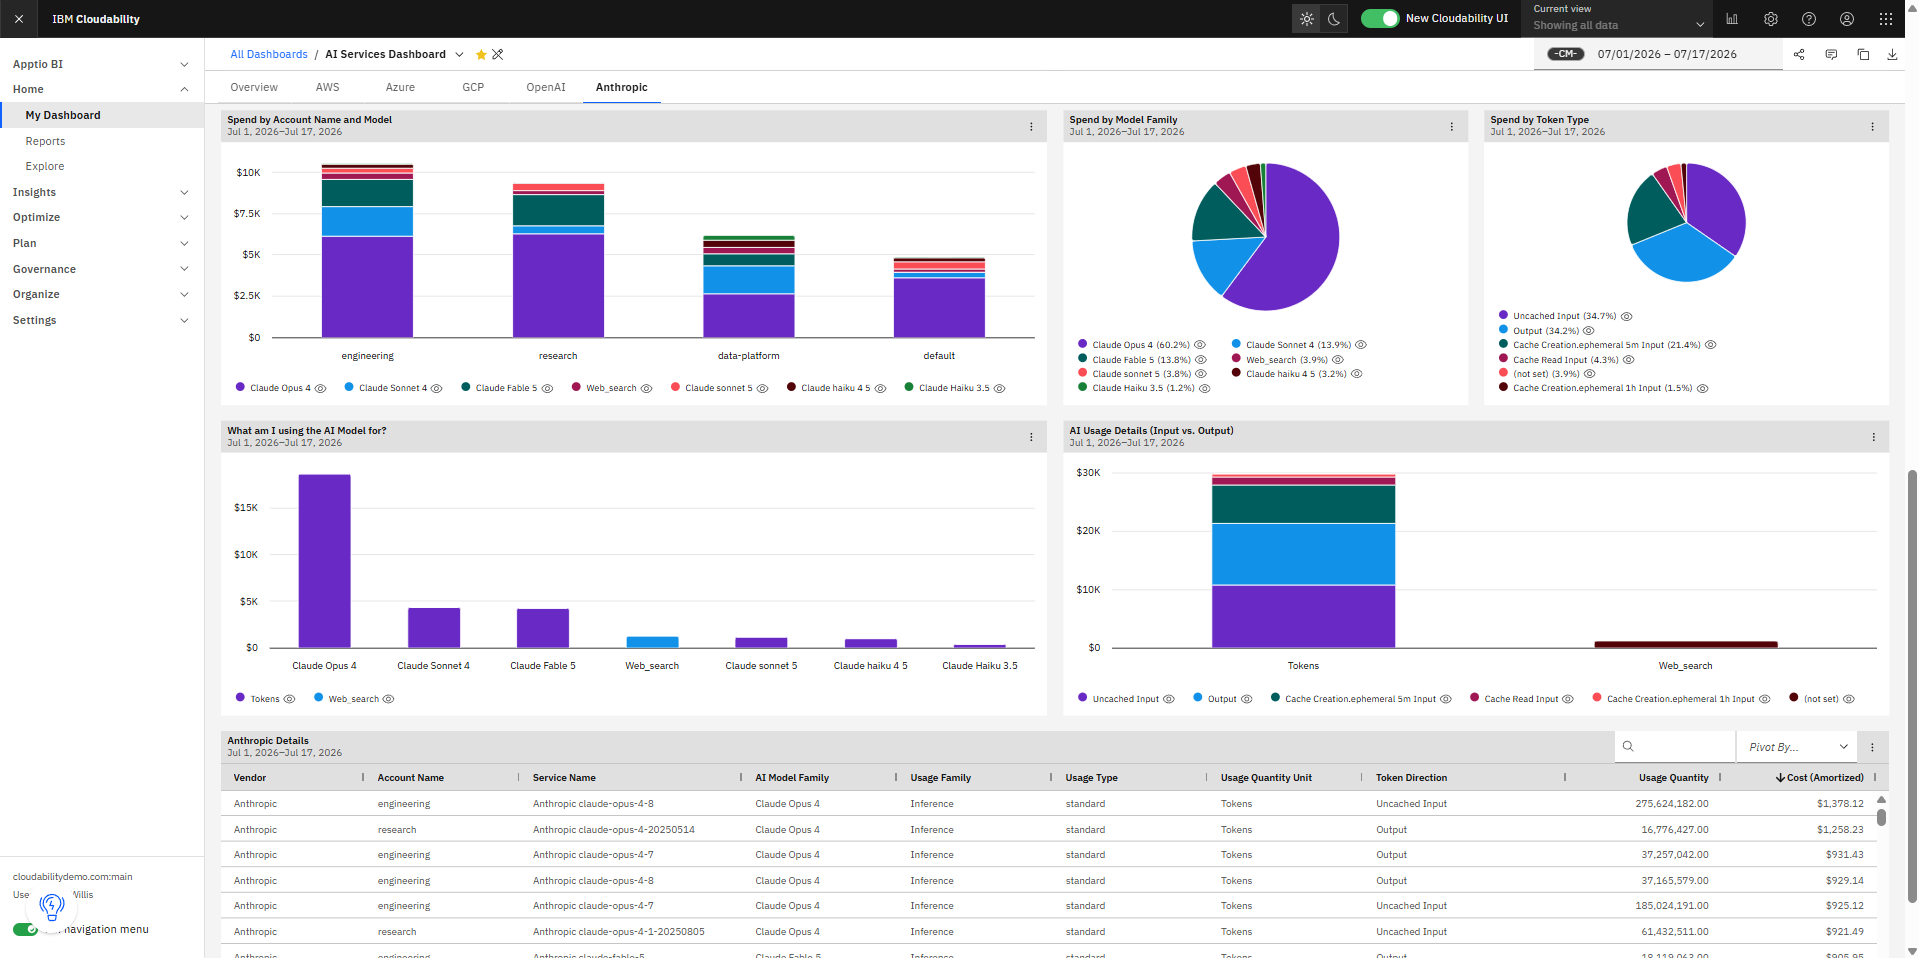
Explore how IBM Cloudability can help your organization connect AI spending to business value.


